Tel Aviv and Stanford Researchers Challenge AI Training Paradigms
For years, the development of artificial intelligence has relied on a singular, massive requirement: the ingestion of nearly every available scrap of data from the real world. From books and websites to images and complex recordings, the prevailing industry standard held that models could only achieve intelligence through exposure to human-generated information. A new study, published as a preprint on arXiv by researchers from Tel Aviv University and Stanford University, now suggests this foundational assumption may be incomplete.
The research team, supervised by Dr. Yoav Levine of the Blavatnik School of Computer Science at Tel Aviv University, explored whether an AI system could develop general learning capabilities using data generated entirely within its own internal environment. As part of his postdoctoral research, Dr. Kfir Dolev worked alongside the Stanford collaborators to test if intelligence contains a “universal” component that functions independently of external data sets.
Two-Model Training Method Generates Internal Sequences
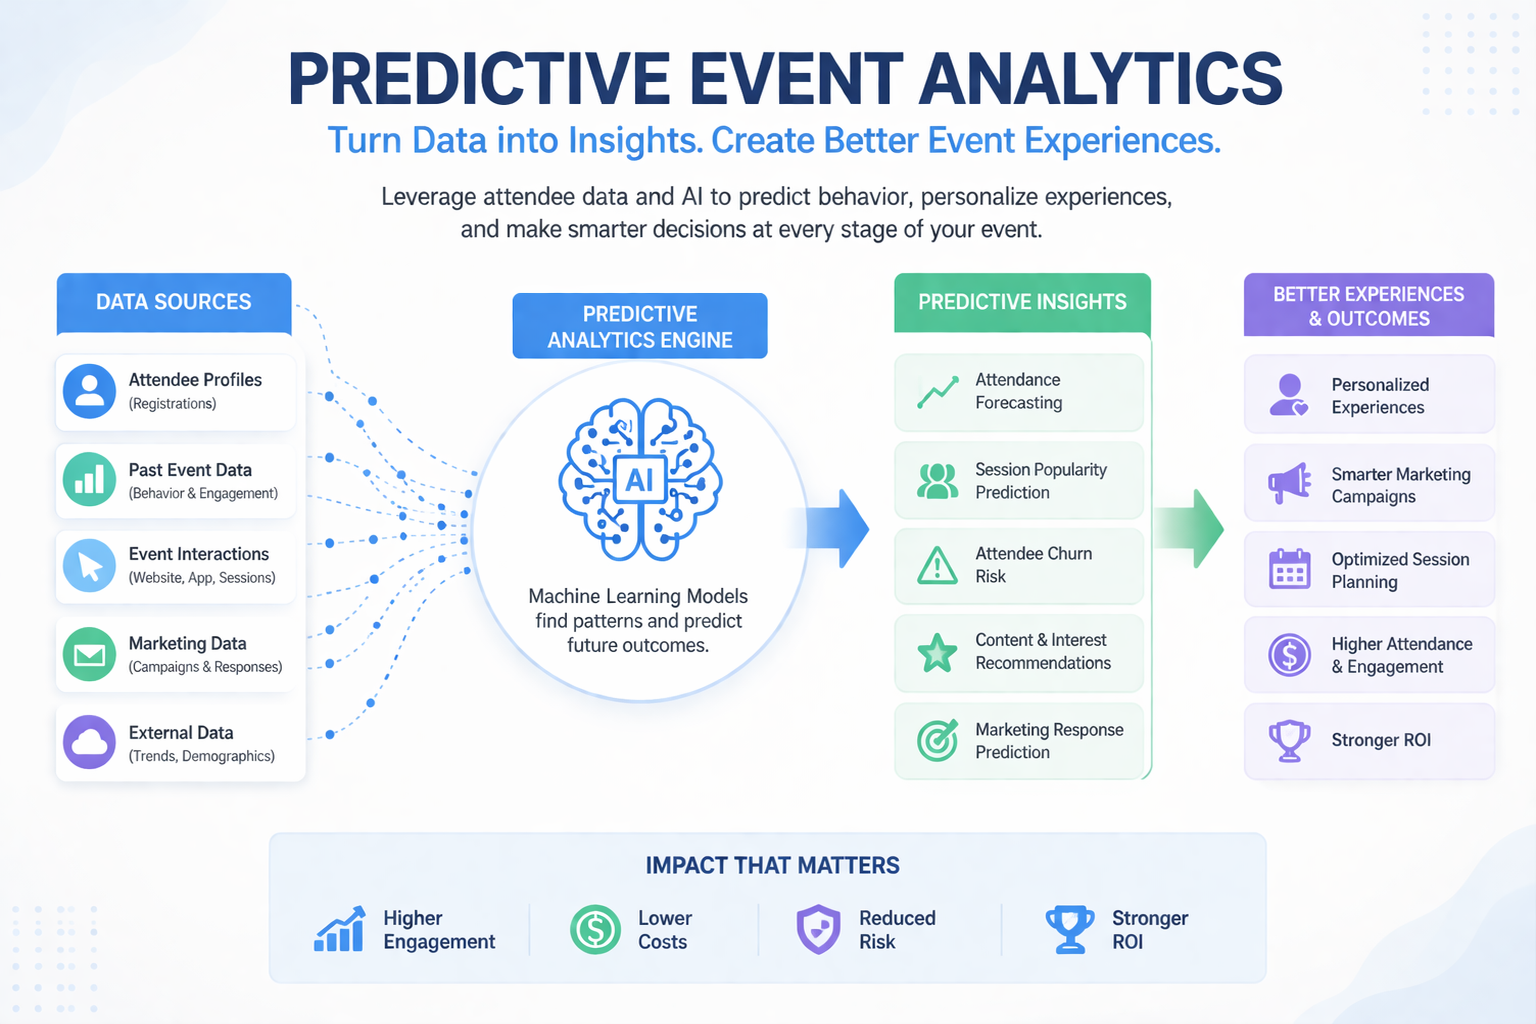
To test this hypothesis, the researchers implemented a training framework where two distinct models learn in tandem from scratch. The first model is tasked with creating short computer programs that produce sequences of symbols. The second model is trained to predict the next symbol in these generated sequences. This process creates a feedback loop: the generator receives information on how effectively its challenges contribute to the learning model’s growth, allowing it to progressively refine the complexity of the exercises to match the evolving capabilities of the second model.
The results of this internal training were unexpected. Without exposure to outside information, the system began to generate its own structured sequences, including familiar mathematical patterns such as the Fibonacci sequence. The system effectively taught itself to produce data that would optimize the learning process for its counterpart.
Predictive Performance Across Real-World Domains
The decisive test for the researchers was whether these internally generated lessons would translate into real-world utility. After the training phase concluded, the team evaluated the model’s performance against a variety of domains it had never encountered, including text, images, music, sounds, code, and DNA sequences. The data indicated that as the team increased the computational resources dedicated to the training process, the model’s predictive capability improved consistently across these diverse fields.
The system also demonstrated an ability to infer rules from examples presented during the testing phase without requiring additional training cycles. According to the study, while the method does not grant a system factual knowledge about the world, it significantly improves the efficiency with which a model can learn from real-world data once that data is introduced.
Future Implications for AI Development
The findings offer a new perspective on the trajectory of machine learning. The researchers emphasize that this is currently a proof of concept involving small models, yet the implications for future scaling are substantial. By identifying general patterns that can be acquired without prior exposure to external information, the study opens a new line of inquiry into how AI might be prepared to process reality more effectively.
For years, the prevailing assumption was that for an AI model to learn anything useful, it first had to be fed enormous amounts of real-world data. In this study, we disproved this fundamental assumption and showed that a model can acquire general predictive skills even when it is trained only on data generated within the learning process itself, said Dr. Yoav Levine.
The research leaves several open questions for the field, particularly regarding the limits of self-generated learning. Future research will likely focus on identifying which universal mathematical patterns emerge as these methods are applied to larger models and determining exactly how far an AI system can evolve before it necessitates direct exposure to the complexities of the outside world.